What Actually Breaks When You Ship a GPT to Production (And How to Stop It)
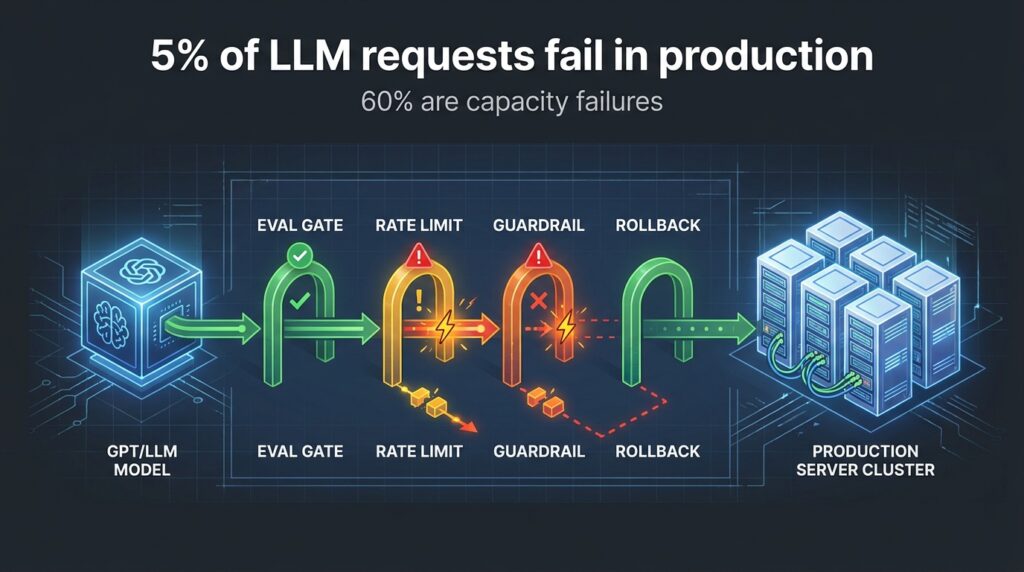
5% of production LLM requests fail. Here’s the operational breakdown — prompt drift, rate limits, rollback complexity — and the engineering controls that stop it.

5% of production LLM requests fail. Here’s the operational breakdown — prompt drift, rate limits, rollback complexity — and the engineering controls that stop it.